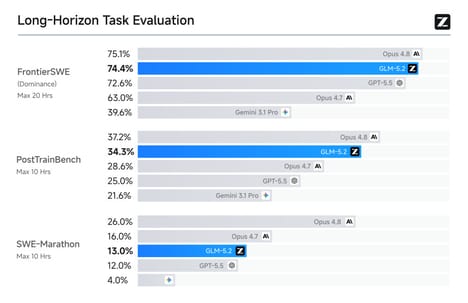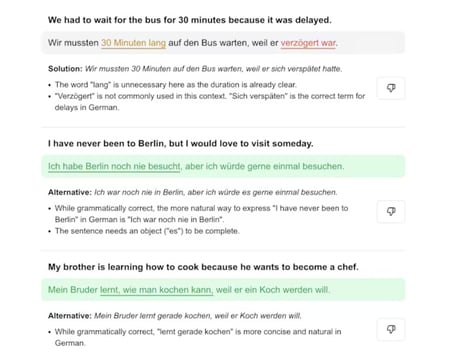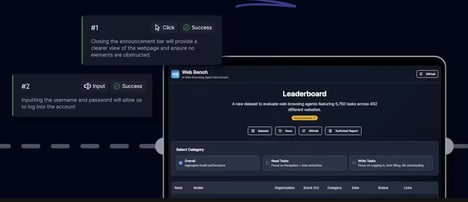
LILT built AURORA to give AI teams a clearer way to compare how agent systems perform outside English, a blind spot that can turn into bad customer-facing decisions. As a multilingual AI leaderboard for frontier models, it ranks systems on non-English work across action-taking and culturally grounded tasks instead of leaning on English-heavy tests.
Because LILT's benchmark tasks are created and checked by native-language domain experts, the scores are closer to the way regional users actually phrase requests and judge answers. LILT also found that coding leaders change by language, so a model choice that looks strongest on a broad chart may not be the best fit for a specific market.
For brands, this turns model selection into a market-by-market decision instead of a single global pick. Teams rolling out multilingual agents can catch weaker performance earlier and set expectations around support, localization, and workflow design with less guesswork.
Image Credit: LILT
Part of the cluster
Autonomy Stacks
AI tools are combining memory, action, and lower-cost execution
Explore the cluster
Why This Trend Is Growing
- Multilingual Model Benchmarking
- Language-specific scorecards reveal performance gaps hidden by English-centric tests, creating room for evaluation platforms tailored to regional customer experiences.
- Localized AI Agent Selection
- Market-by-market model comparison reframes AI deployment as a localization challenge where enterprises can match agents to cultural context, workflows, and user intent.
- Native-expert Evaluation
- Benchmarks created and reviewed by domain-fluent speakers make AI quality measurement more realistic, opening space for trusted validation networks across global markets.
Industries Being Reshaped
- Artificial Intelligence
- Frontier model providers face rising demand for multilingual transparency as buyers prioritize systems that perform reliably across non-English tasks and regions.
- Localization Technology
- Translation and localization vendors can extend into AI readiness assessment as companies require culturally grounded testing before launching automated agents.
- Customer Experience
- Global support teams gain more precise insight into where AI agents may fail, enabling differentiated service design for multilingual users.