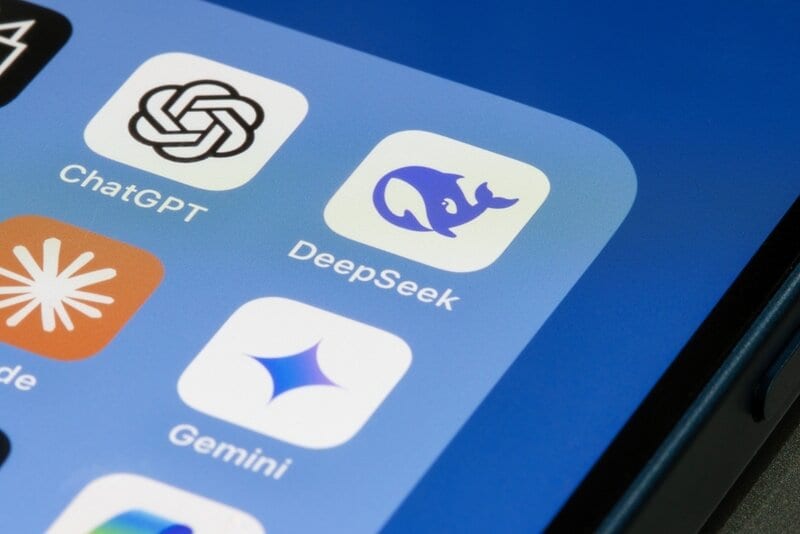
DeepSeek is expanding access to open-source inference tools with ‘DeepInfer,’ a free framework designed to run its ‘V4.1-Flash’ model. It gives AI teams a way to deploy trained models for output generation while aiming to reduce compute use, energy demand and overall operating costs.
The tool currently supports only ‘V4.1-Flash,’ with future models to be added as they become available. DeepSeek also highlights speculative decoding, a method that speeds up generation by predicting likely next steps before confirming them.
At $0.035 per million input tokens, ‘V4.1-Flash’ sits well below many frontier-model prices and makes cost control a core part of the product story. That pricing turns inference into a sharper competitive lever, especially for businesses weighing closed systems against cheaper open-source alternatives.
Image Credit: Tada Images
Why This Trend Is Growing
- Low-cost AI Inference
- Falling token prices create room for businesses to embed generative AI into high-volume workflows that were previously limited by compute economics.
- Open-source Model Deployment
- Freely available inference frameworks shift control toward internal AI teams by reducing dependence on closed vendor ecosystems.
- Speculative Decoding Acceleration
- Faster output generation through predictive processing points to more responsive AI products across customer service, coding and real-time knowledge tools.
Industries Being Reshaped
- Enterprise Software
- Cost-efficient inference enables software platforms to add AI features at scale without dramatically increasing subscription or infrastructure costs.
- Cloud Computing
- Lower compute and energy requirements reshape demand for AI infrastructure by favoring optimized deployment layers over raw capacity expansion.
- Data Center Operations
- Energy-conscious inference frameworks introduce new efficiency benchmarks for facilities supporting large-scale model serving.