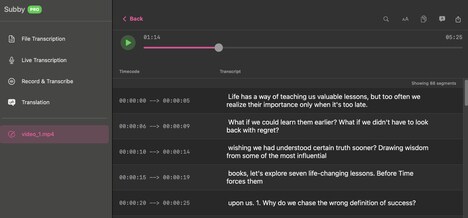
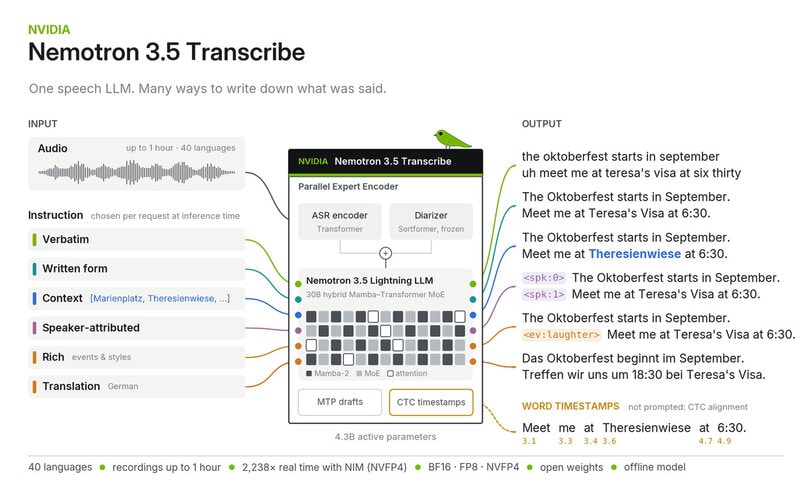
Nvidia has introduced 'Nemotron 3.5 Transcribe,' a free, open-weight speech-to-text model for developers building business meeting and medical transcription apps. It works with recorded files instead of live audio and can transcribe up to 40 languages into text while separating as many as eight speakers.
An updated 'Granary' speech dataset accompanies it, and the model can translate recordings between English and other supported languages. These capabilities let teams train apps on industry jargon and long-form recordings in different languages, instead of settling for more generic recognition across every field.
Recorded-only audio keeps Nemotron 3.5 out of live voice-agent workflows, but its open-weight format enables more specialized tuning for workplace transcription. Single-chip deployment makes custom speech recognition a broader practical infrastructure option, from robotics hardware to data center systems.
Image Credit: TechCrunch/AI generated
What's Driving This Trend
- Open-weight Speech Models
- Accessible model weights create room for domain-specific transcription systems that outperform generic tools in specialized business, medical, and technical environments.
- Multilingual Meeting Intelligence
- Cross-language transcription and translation expand the value of recorded meetings by turning global conversations into searchable, structured workplace knowledge.
- Speaker-separated Audio Analytics
- Automated speaker diarization enables richer analysis of multi-person recordings, supporting clearer accountability, compliance review, and conversational insight extraction.
Who This Affects Most
- Enterprise Software
- Workplace platforms can embed customized transcription into collaboration, documentation, and knowledge-management products for teams handling complex terminology.
- Healthcare Technology
- Medical transcription providers gain opportunities to adapt speech models around clinical jargon, multilingual patient interactions, and long-form recorded consultations.
- Data Center Infrastructure
- Single-chip deployment makes specialized speech recognition more practical for scalable infrastructure offerings across private clouds, robotics systems, and enterprise AI stacks.